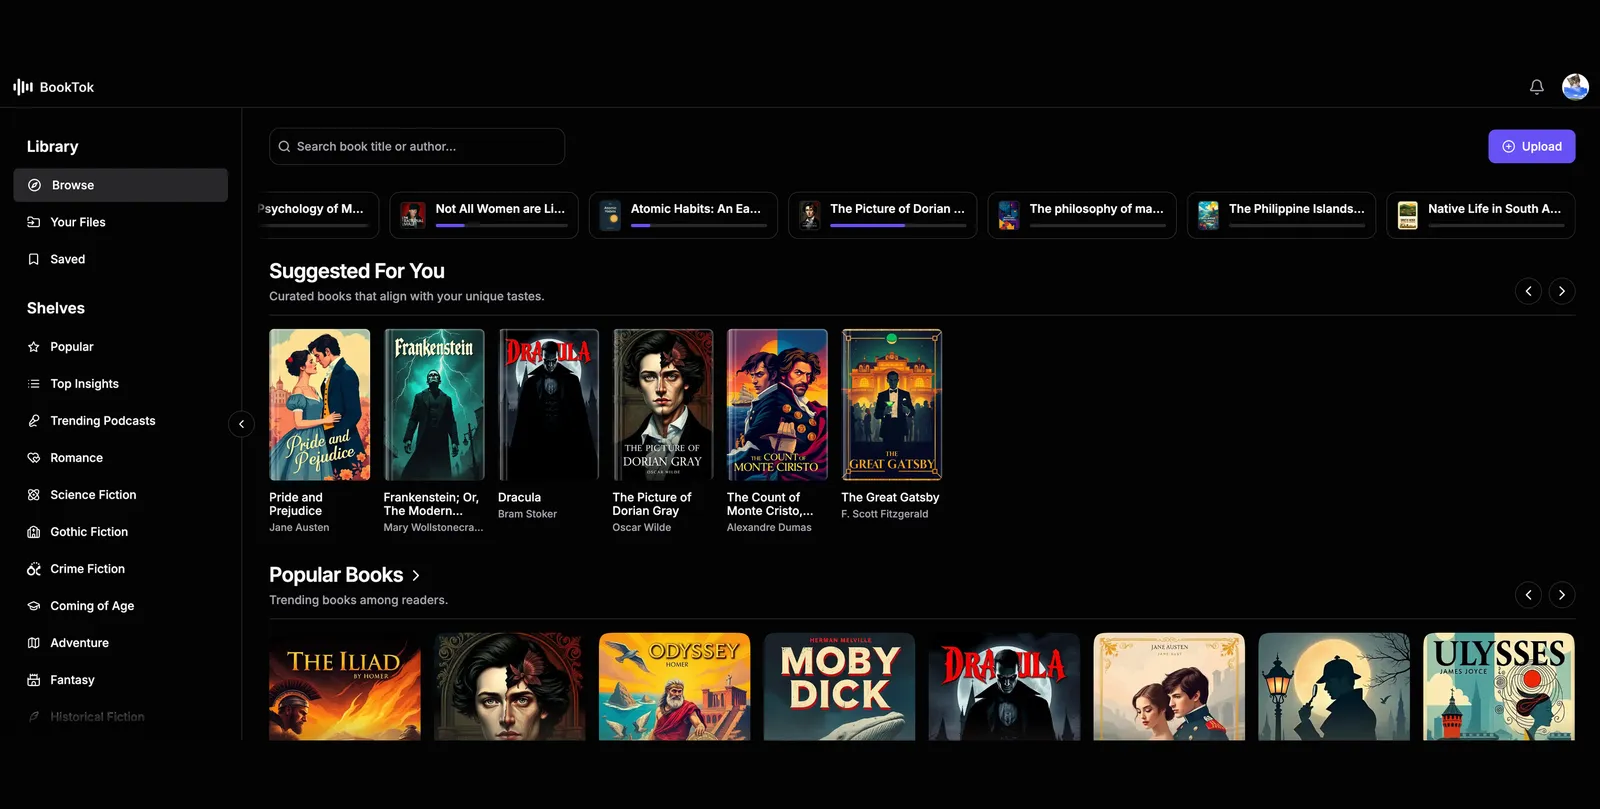
Fill a new reading and listening app with a usable catalog, and give search something good to work with.
Deployed
Python scrapers and batch tools for metadata, audiobook processing and subtitle generation, OpenAI-based topic tagging, and Supabase for storage.
Outcome
300,000+ public-domain books with the metadata the app needed, plus faster, more relevant keyword search and early recommendation experiments.
The job
Every title needed the same handful of things before it was useful in the app: clean metadata, processed audio, subtitles, a topic and a genre. At 300,000 books, “by hand” stops being an option and starts being a joke.
What I built
Scrapers that collected public-domain books and their metadata.
Audiobook processing and subtitle generation so titles could be listened to and followed along.
Topic and category assignment from book descriptions using the OpenAI API, with resumable runs and retries so a long batch survives a bad minute. A version of this is public: Book Topics Assigner (opens in a new tab).
Genre conversion and Supabase file uploads to land everything where the app could read it.
Recommendation experiments, including a content-based engine that suggests books from a reader’s history. The public version: Books Recommender (opens in a new tab).
What changed
The catalog existed, the metadata was consistent enough to search, and keyword search got faster and more relevant. None of those books had to be opened by a person to get there.